
From Model to API
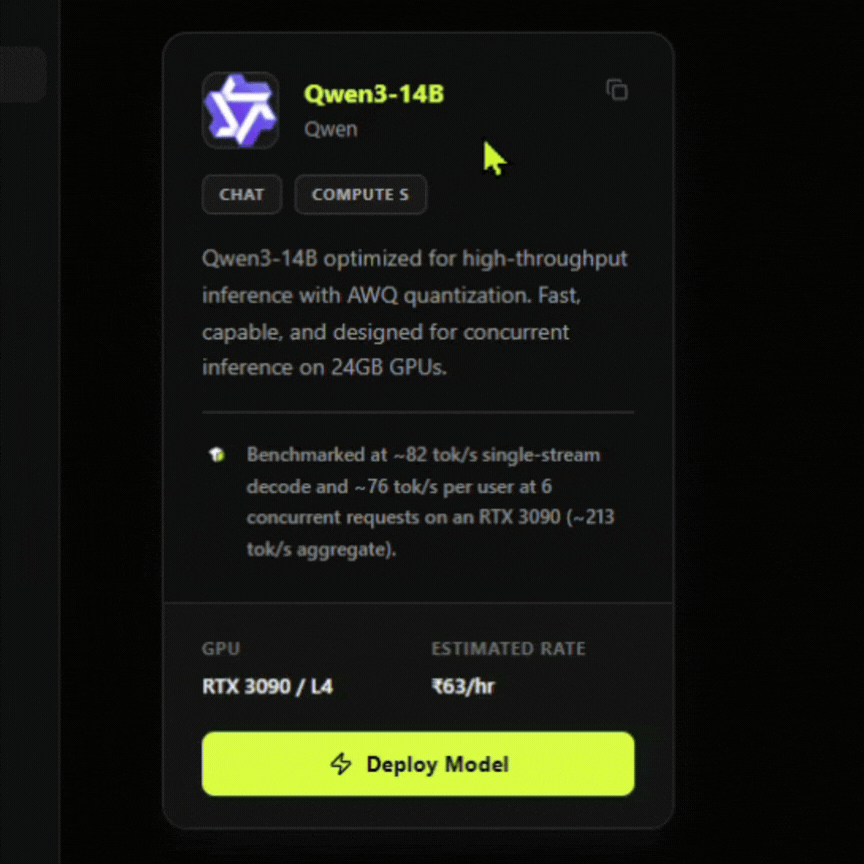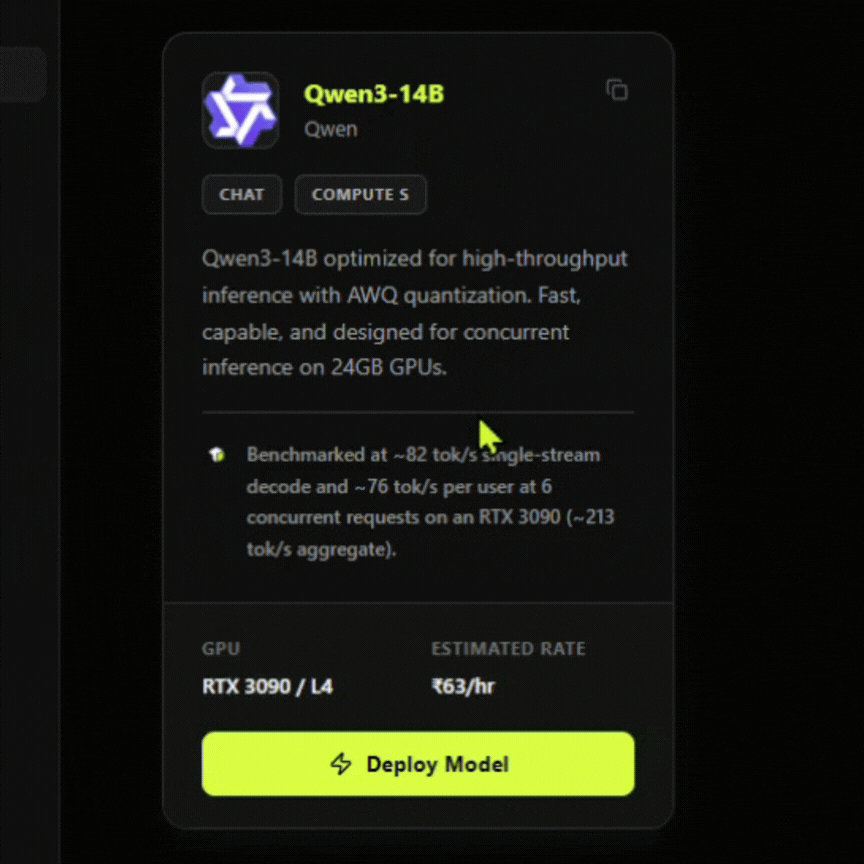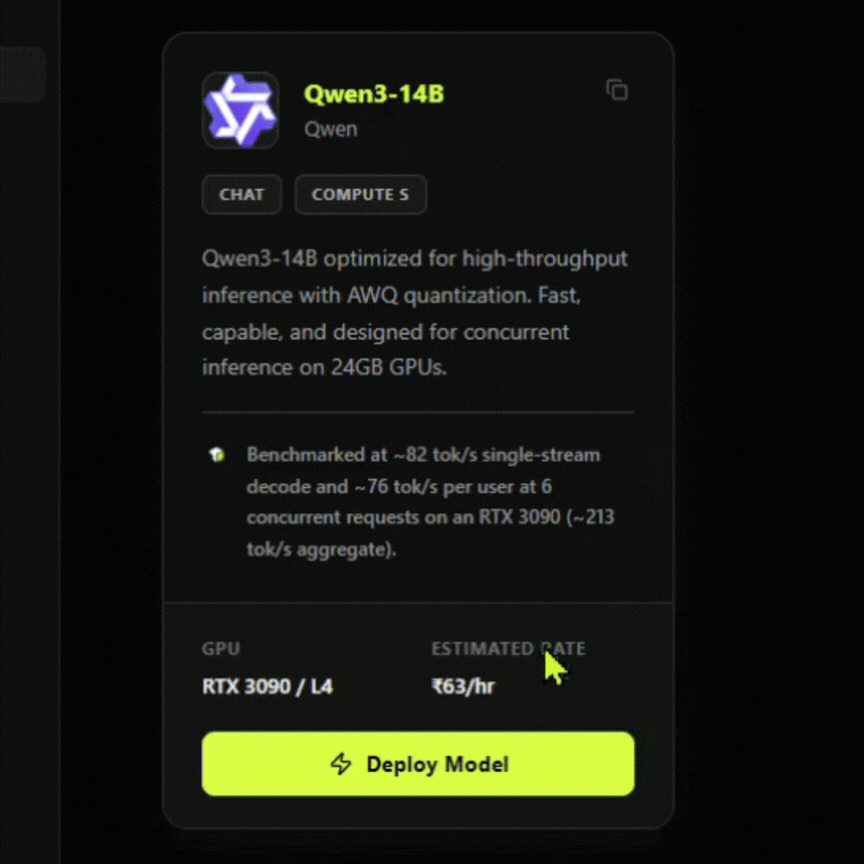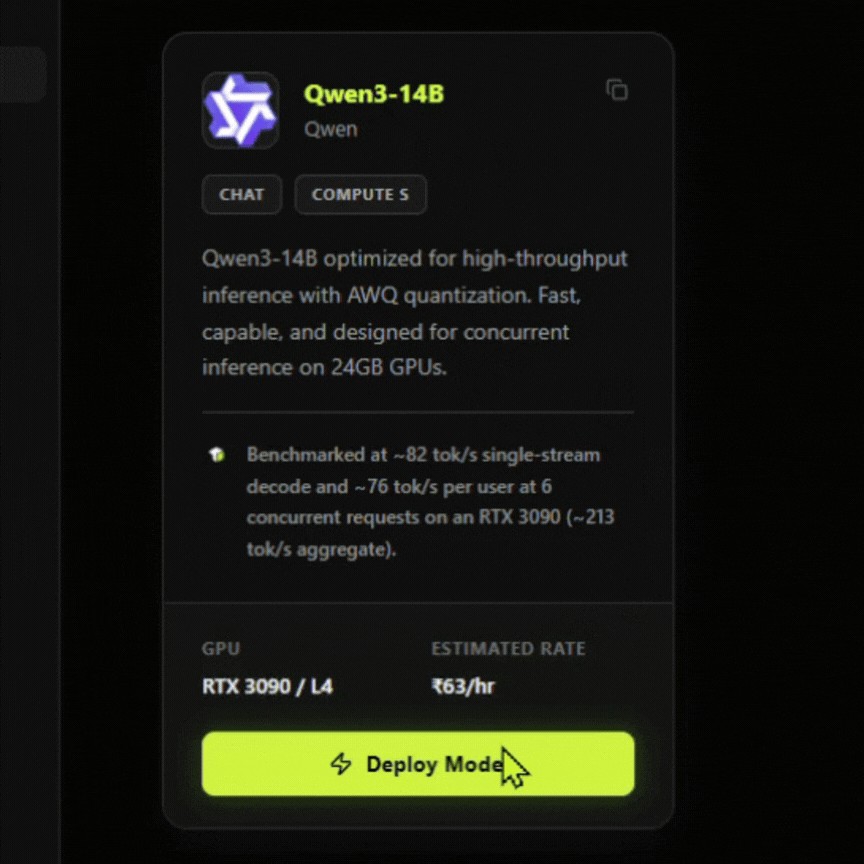
01Choose a model
Select from Tolka Edge's curated, deployment-ready models.
02Deploy a Rig
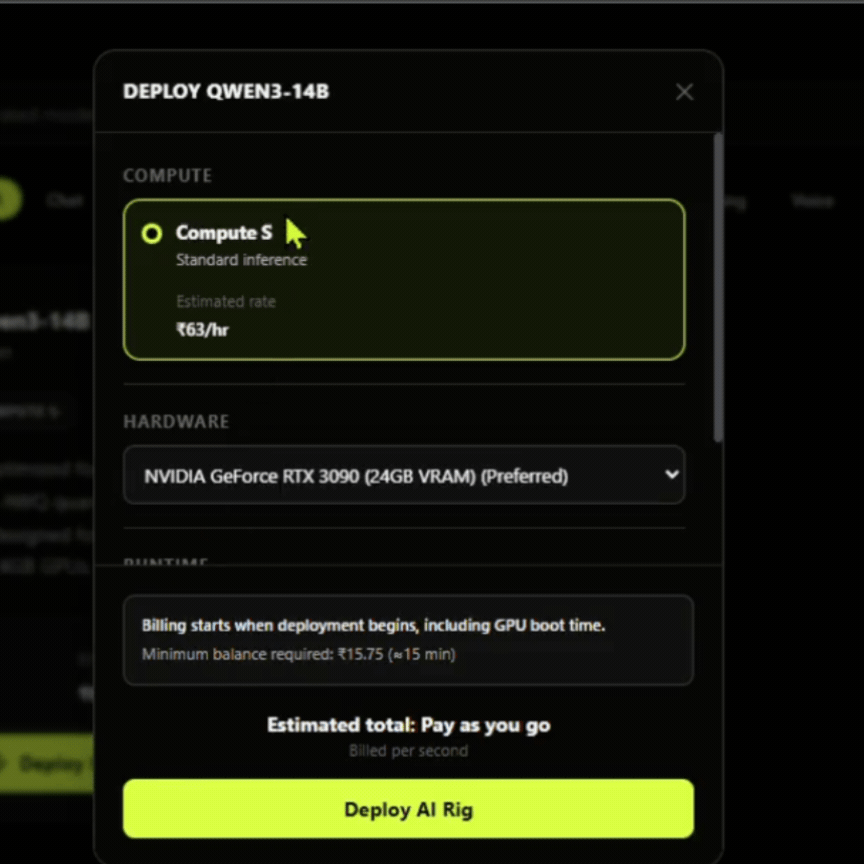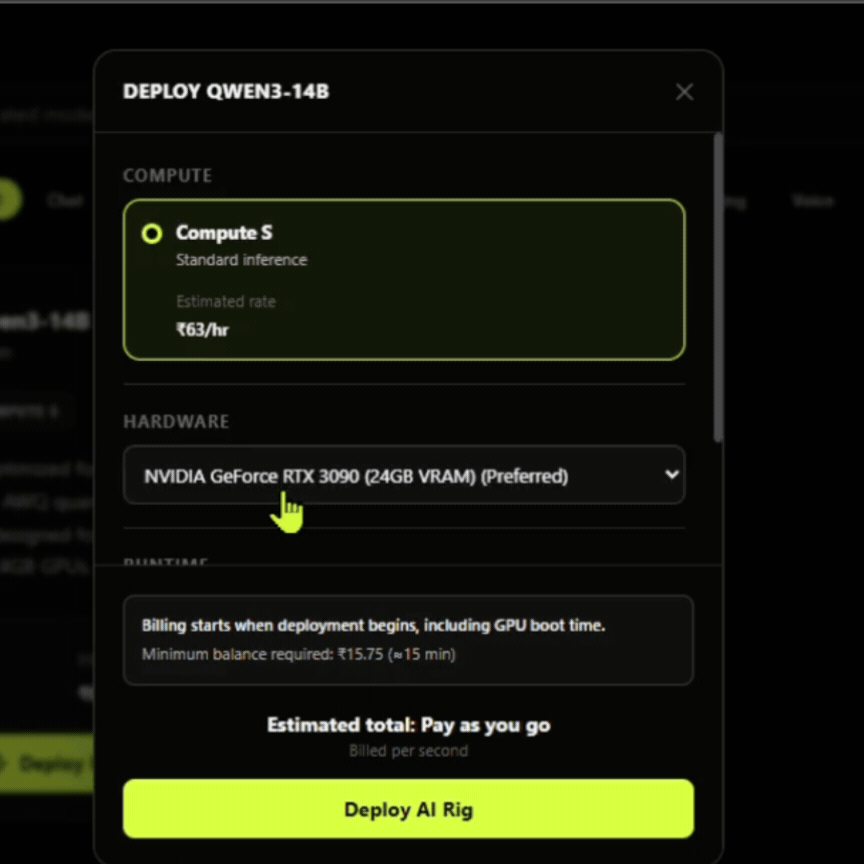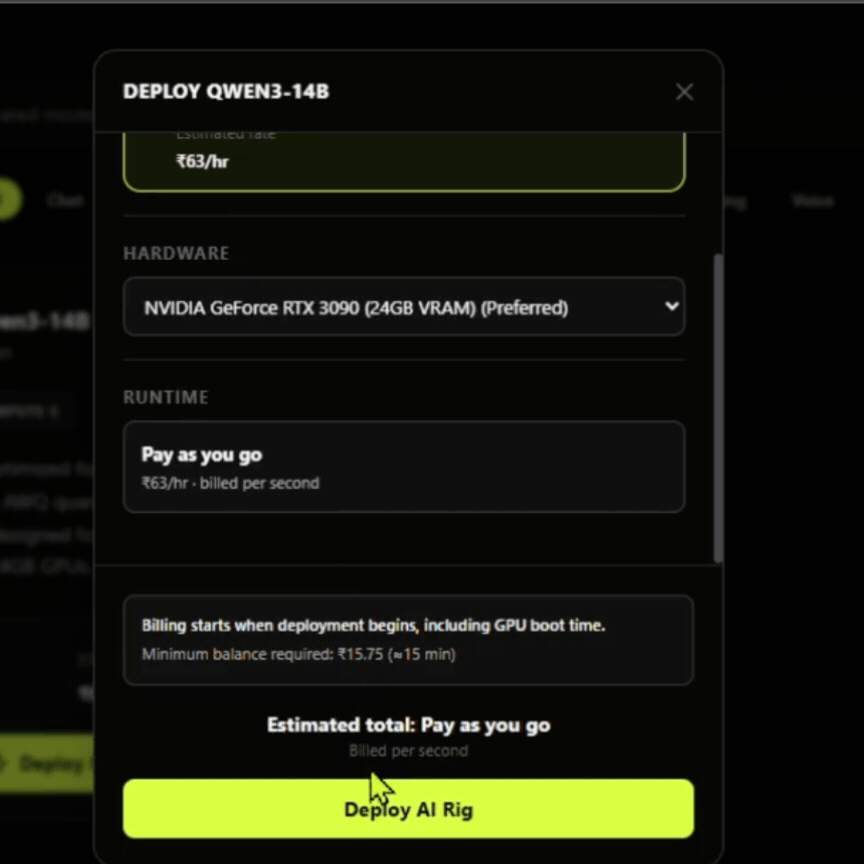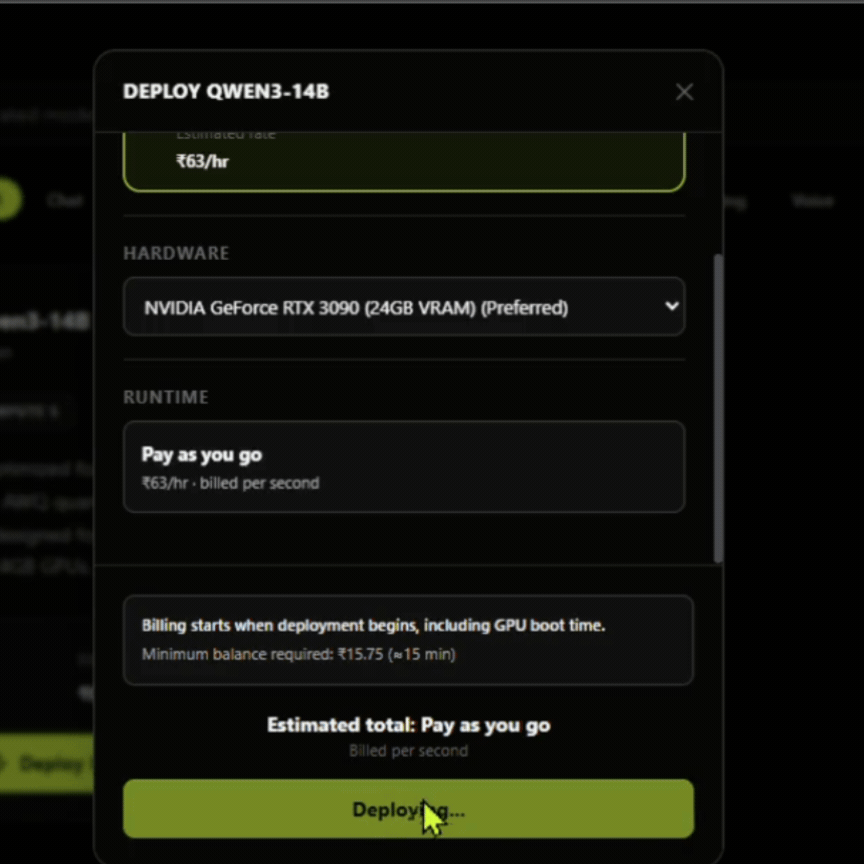
Choose a supported GPU and deploy your dedicated inference environment with one click.
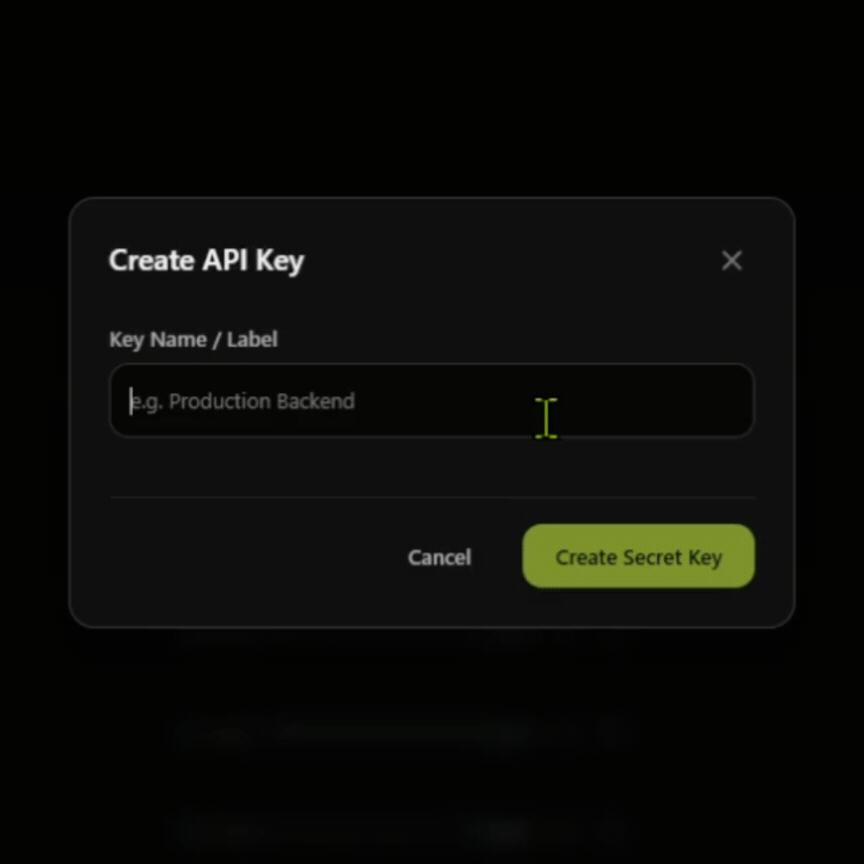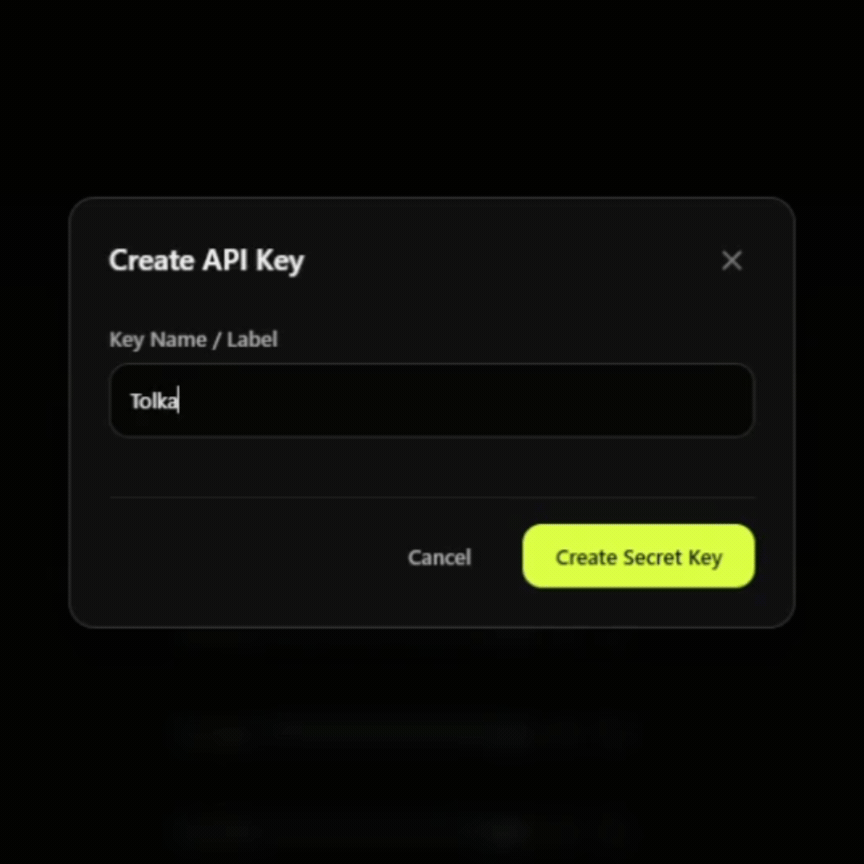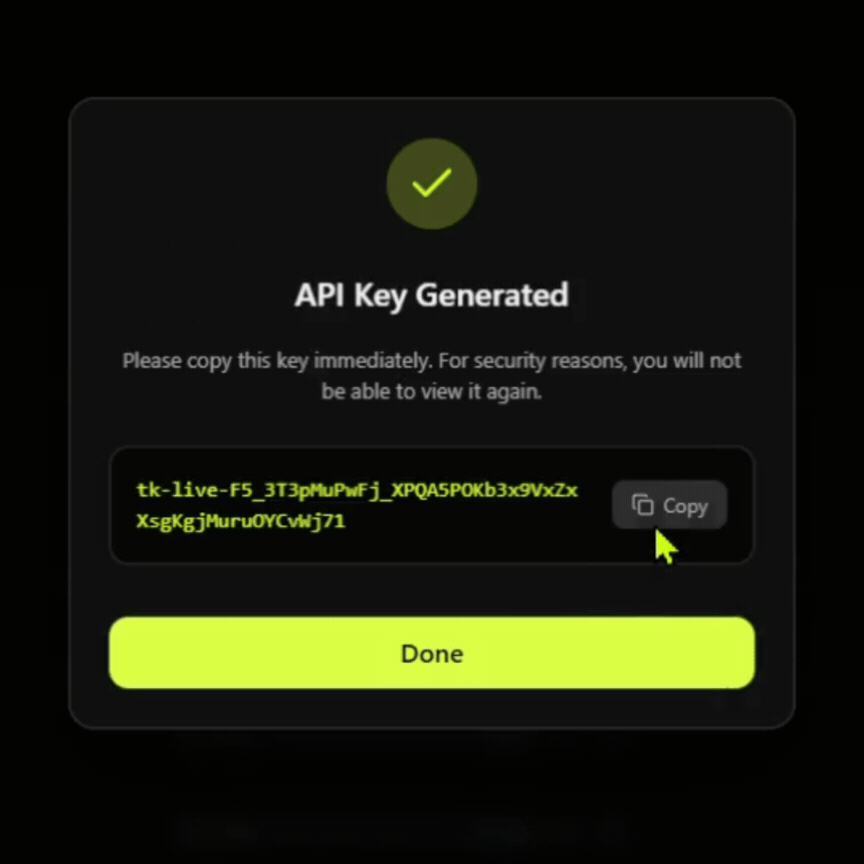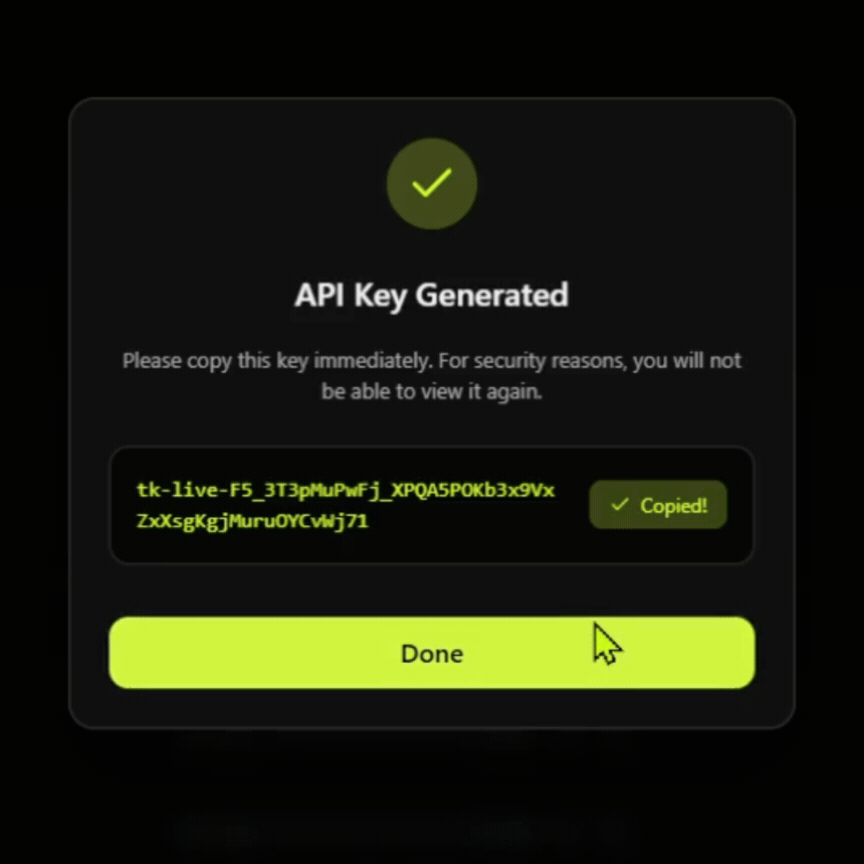
03Get your API
Use your Rig through an OpenAI-compatible endpoint with the tools and SDKs you already use.
Curated Models
We don't throw thousands of models at you.
Tolka Edge provides curated models configured for supported GPU hardware and automated deployment.
Available now
Qwen3-14B
A 14B Qwen model served with AWQ quantization and optimized vLLM inference for 24GB-class GPUs.
More models are being added to the catalog.
Simple Pricing
Pay As You Go
GPU time, not token billing. Your Rig is billed based on its active runtime and charges are tracked to the second.
Frequently Asked Questions
Is the API OpenAI compatible?
Yes. Tolka Edge provides an OpenAI-compatible API for supported models.
Do I pay per token?
No. Dedicated Rigs use time-based GPU billing. You pay for the active runtime of your Rig.
What models are available?
Tolka Edge currently offers Qwen3-14B. More curated models are being added.
What GPUs can I use?
Available GPU options depend on the model's verified hardware configuration. Supported choices are shown during deployment.
How long does deployment take?
Deployment time depends on GPU availability, infrastructure provisioning, and model startup. Cold starts can take several minutes.
Is the GPU dedicated?
Yes. A deployed Rig is allocated to your deployment rather than shared inference capacity.